Structure where texture is weak
Explicit edge features expose colon folds and high-frequency boundaries that are difficult to recover from raw, low-texture RGB alone.
Pose Refinement with Intrinsic Shading and edge Maps
Multi-Modal Monocular Endoscopic Depth and Pose Estimation with Edge-Guided Self-Supervision
PRISM is a self-supervised framework for monocular depth and camera-pose estimation in colonoscopy. It supplements RGB images with two complementary cues: intrinsic shading supports depth prediction, while structural edge maps guide pose estimation.
The method is designed for difficult endoscopic scenes containing weak texture, non-uniform illumination, specular reflections and domain variation.
Qualitative comparisons show how explicit structural and illumination cues preserve colon geometry across low-texture regions, reflections and changing appearance.
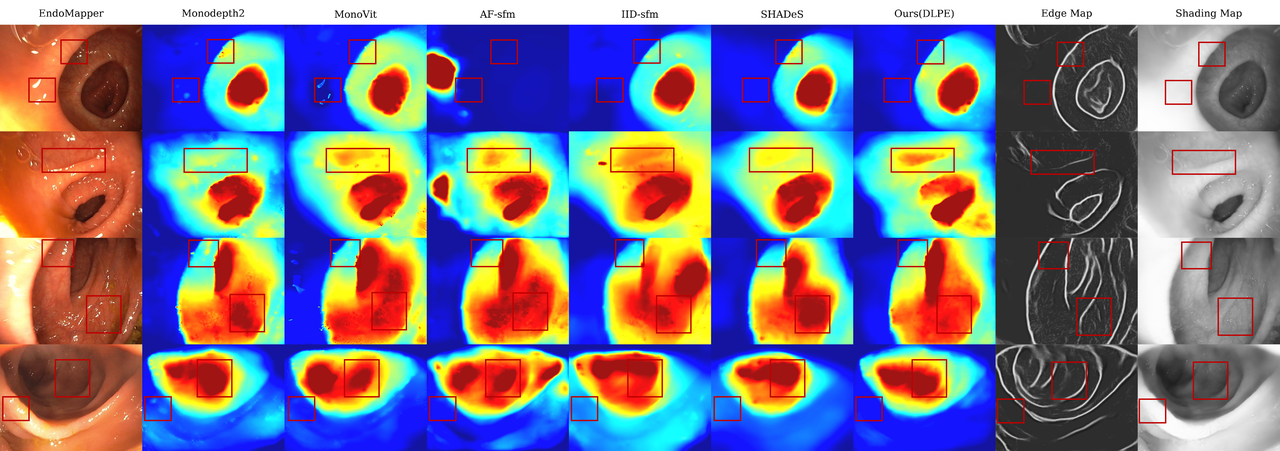
Models are trained on real Hyper-Kvasir video and evaluated on the C3VD test set. PRISM achieves the lowest RMSE, LogRMSE, MAE and SqRel among the compared methods, while remaining competitive in camera trajectory estimation.
| Method | RMSE ↓ | LogRMSE ↓ | MAE ↓ | AbsRel ↓ | SqRel ↓ | ATE ↓ |
|---|---|---|---|---|---|---|
| Monodepth2 | 6.3138 | 0.1841 | 4.3699 | 0.1501 | 1.0168 | 2.7025 |
| MonoViT | 6.8544 | 0.1789 | 4.6146 | 0.1473 | 1.0958 | 2.4298 |
| SHADeS | 7.1065 | 0.1845 | 4.7230 | 0.1500 | 1.1437 | 1.2533 |
| PRISM | 6.1246 | 0.1830 | 4.3300 | 0.1475 | 1.0010 | 1.9077 |
Selected metrics from the paper's C3VD comparison. Lower is better.
The three-stage pipeline first produces shading and edge modalities, then jointly learns depth and pose through view synthesis, and finally refines pose while keeping the learned depth representation fixed.
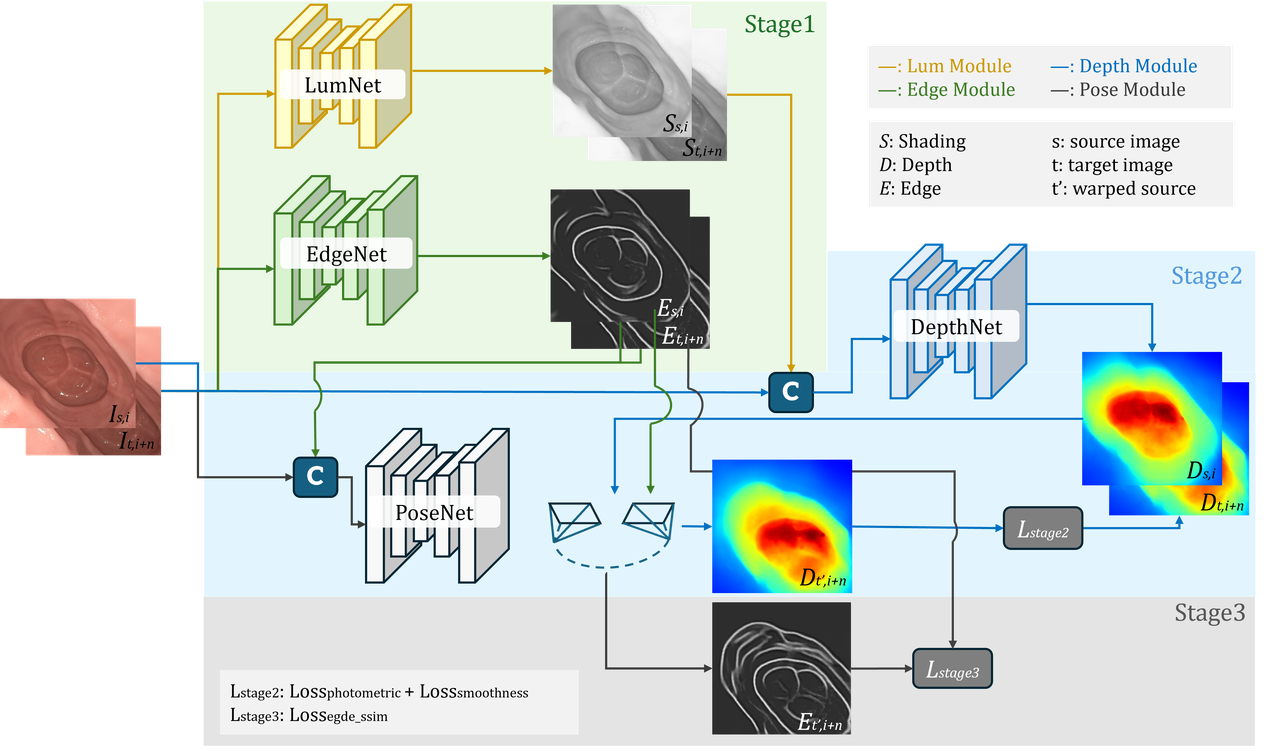
Explicit edge features expose colon folds and high-frequency boundaries that are difficult to recover from raw, low-texture RGB alone.
Intrinsic shading separates useful shape cues from reflectance, giving depth estimation a stronger signal under complex endoscopic lighting.
Stage-wise learning couples depth with edge-guided pose refinement to improve geometry and camera trajectories across challenging domains.
If you use PRISM in your research, please cite:
@article{ju2026prism,
  title={Multi-modal monocular endoscopic depth and pose estimation with edge-guided self-supervision},
  author={Ju, Xinwei and Daher, Rema and Stoyanov, Danail and Bano, Sophia and Vasconcelos, Francisco},
  journal={International Journal of Computer Assisted Radiology and Surgery},
  year={2026},
  doi={10.1007/s11548-026-03669-1}
}